About ClusterTriage

Deep experience.
Narrow focus.

ClusterTriage is built around one specialist problem space: Microsoft failover-cluster infrastructure. The proposition is intentionally narrower than a general infrastructure consultancy because the value comes from repeatable depth.

Specialists should be able to show their method.

ClusterTriage combines long-term Microsoft infrastructure experience with a repeatable measurement and reporting method. The aim is not to produce the largest possible report, but to establish what the environment is actually doing, what matters operationally and whether remediation changed the measured state.

The same philosophy runs through the annual Assurance service and the incident-focused ClusterDown entry point: evidence first, judgement second, recommendations that can be verified.

Leadership

The people behind ClusterTriage.

Two different technical backgrounds, one common focus: deep cluster analysis that leads to actionable, verifiable improvement.

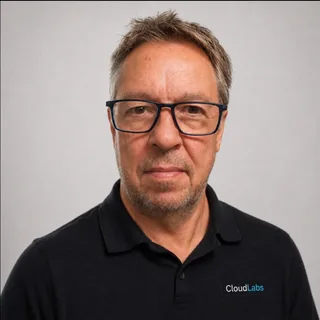
Hans Vredevoort

Hans Vredevoort

Server & Cluster Engineering

40+ years of experience in the Microsoft world. Infrastructure projects from SMB to enterprise and more than ten years as a Microsoft MVP across Failover Clustering, Virtual Machine and Cloud & Datacenter Management.

Co-author of Microsoft Private Cloud Computing: Building the Foundation, technical editor of Mastering Hyper-V Deployment, contributor and reviewer of the Windows Server 2012 Hyper-V Installation and Configuration Guide, co-founder of Hyper-V.nu and co-host of Hyper-V Amigos.

Windows ServerHyper-VFailover ClusteringStorage Spaces DirectAzure LocalSystem Center VMMPowerShellRDMASANMigration & Upgrades
LinkedIn profile →
Rob Scheepens

Rob Scheepens

Performance, observability & Windows internals

Rob brings a strong background in performance, observability and Windows internals, with extensive experience around Microsoft platforms and enterprise infrastructure.

His technical focus is on complex performance and infrastructure problems and on making production behaviour measurable.

PerformanceObservabilityWindows InternalsHyper-VWindows ServerVirtualisationDiagnosticseBPF
LinkedIn profile →

ClusterTriage

Measure the environment. Make the reasoning visible.

That principle is the common thread across our Assurance, Method and incident work.