Server & Cluster Specialist
Hans Vredevoort
40+ years in Microsoft infrastructure, more than a decade as a Microsoft MVP and a long track record in Failover Clustering and Hyper-V.
LinkedIn profile →Windows Failover Cluster engineering
ClusterTriage turns live configuration into defensible findings, priorities and verified improvement. We focus on the cluster stack where small inconsistencies become large operational risks: Windows Server, Hyper-V, storage, networking, hardware and Azure Local.
Measure · Analyse · Prioritise · Remediate · Verify · Repeat
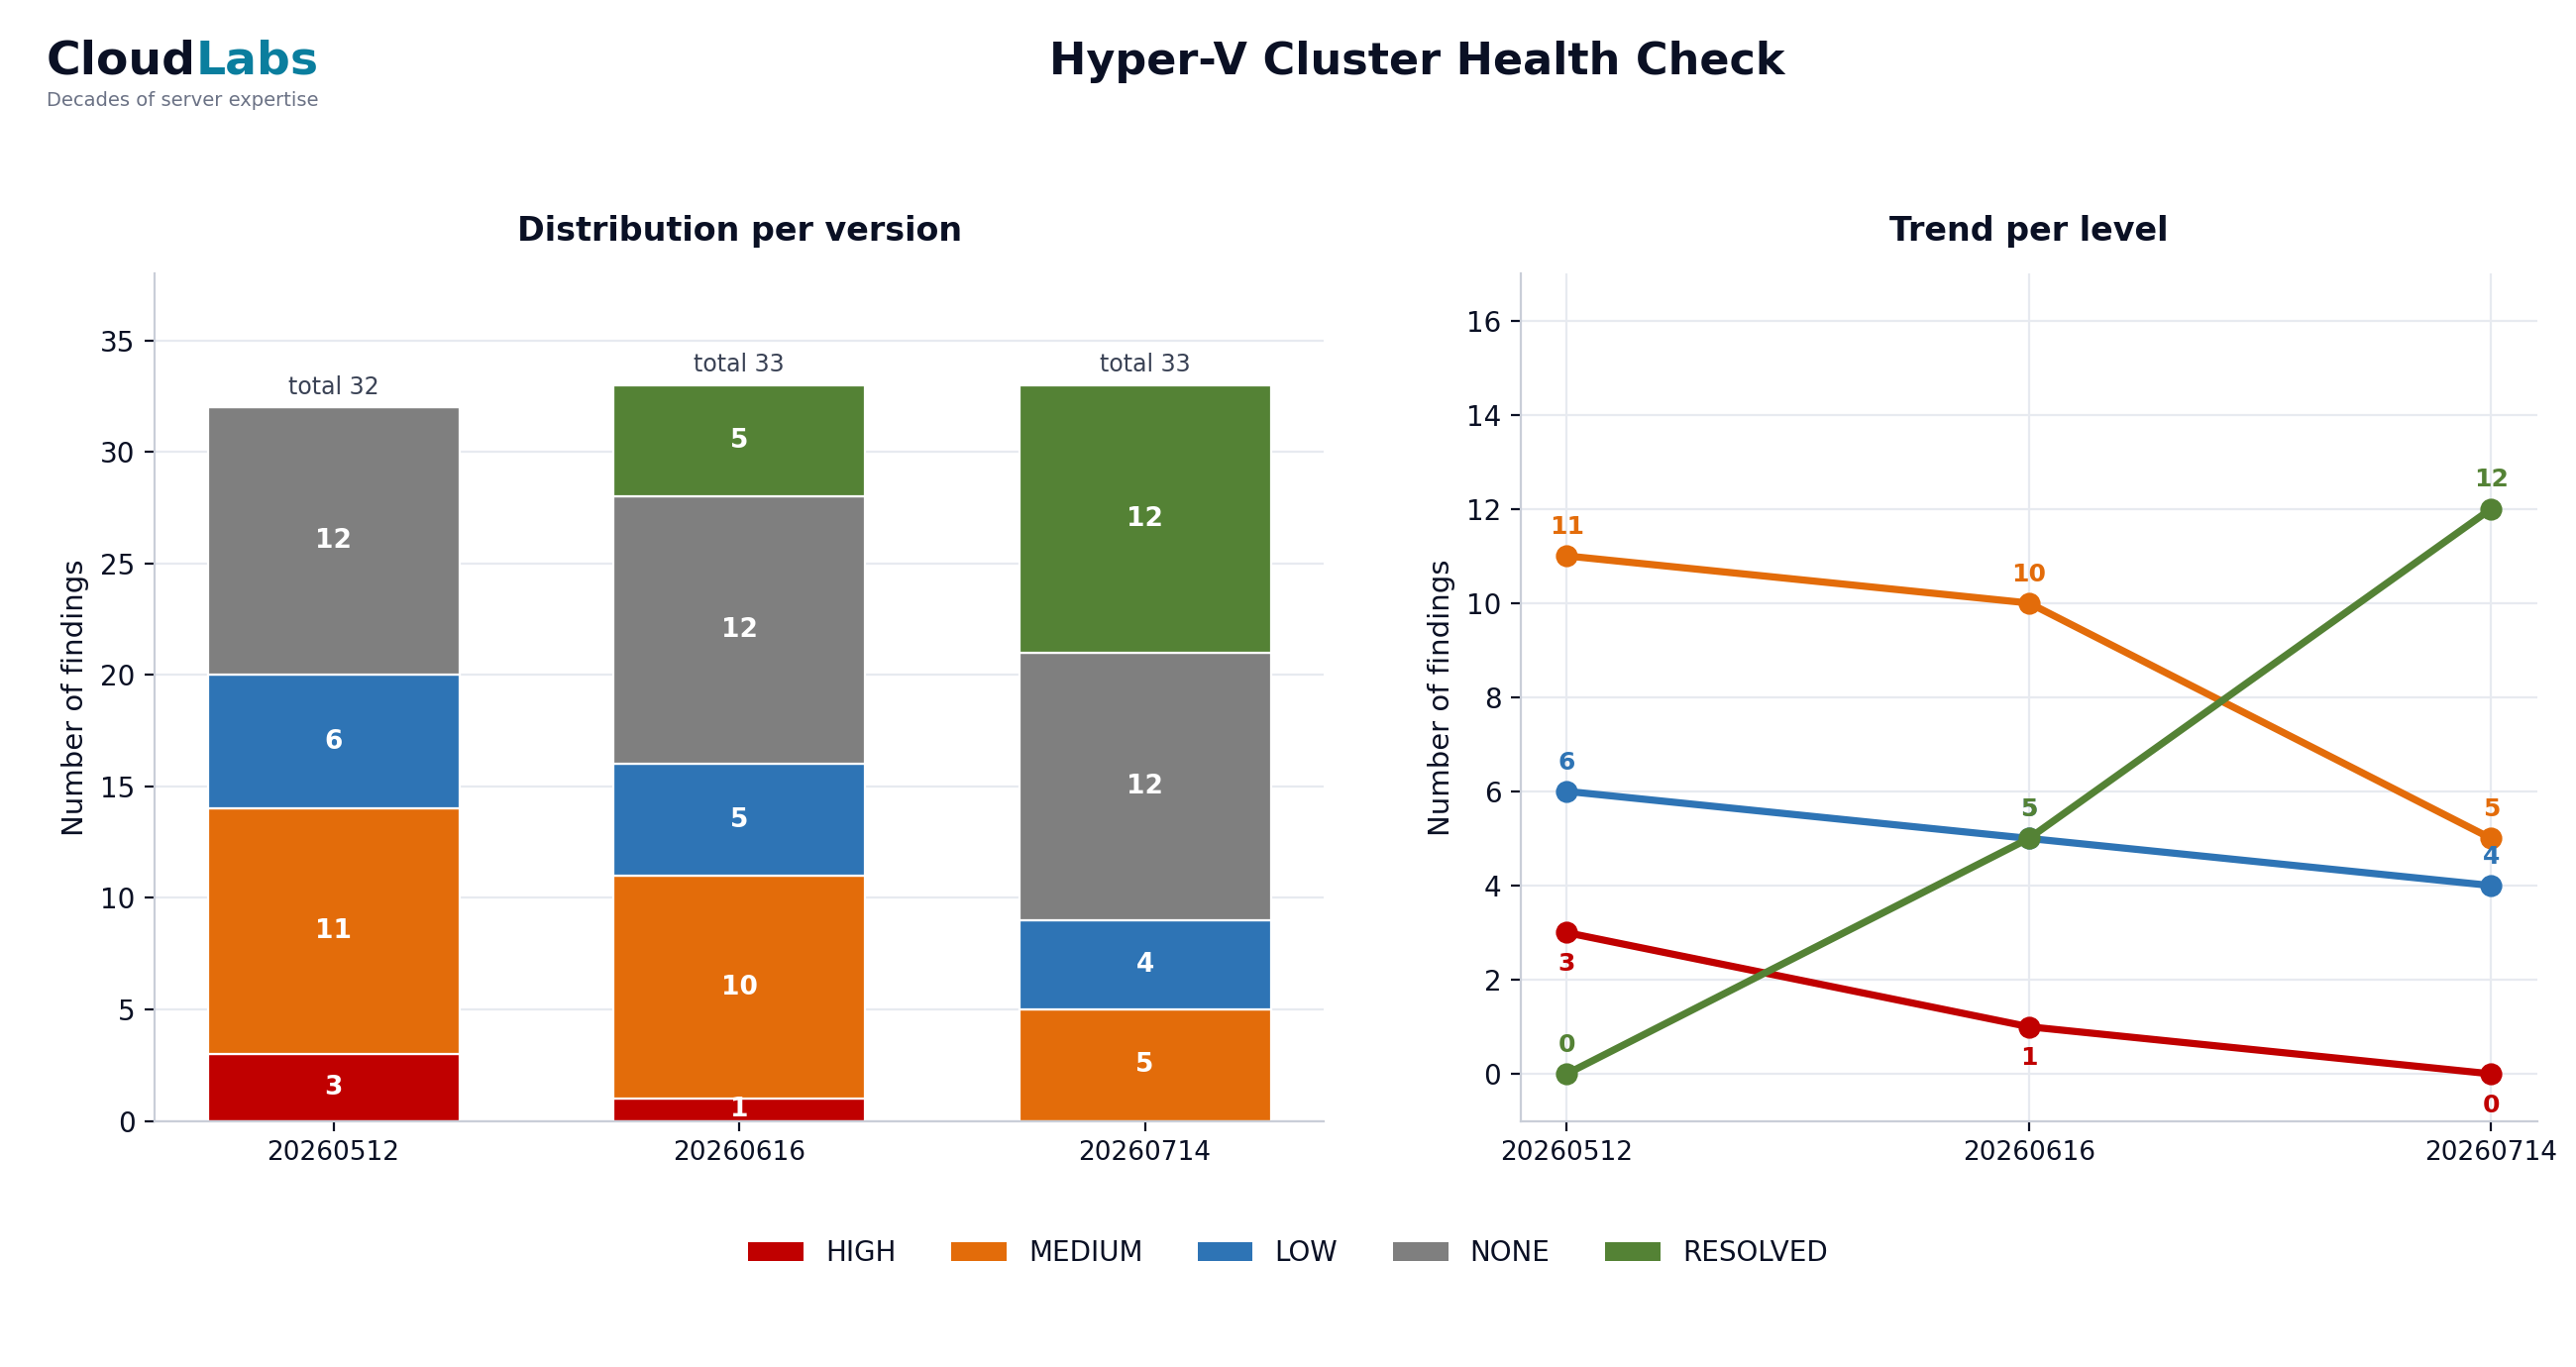
Active incident? Preview the separate ClusterDown incident route →The yearly cycle shows whether remediation actually changed the measured state.
Three clear entry points
The brand is built around one specialist domain, but the buyer journeys are deliberately separated.
A one-year programme that establishes the baseline, verifies remediation and exposes configuration drift over four measurements.
Explore Assurance →02 · METHODSee the real toolchain from intake and collectors through grading, findings, reports and the feedback loop into remediation.
Open Method →03 · INCIDENTA separate, incident-focused route for a cluster that is down or unstable now. Preserve evidence first, then decide how deep the investigation must go.
Preview ClusterDown →Not a black box
The Method page uses the actual ClusterTriage toolchain. It shows what enters the process, which modules measure which parts of the estate, how measured state becomes a finding and which documents come out.
Every magnifier opens the underlying module, catalogue, register or report view.
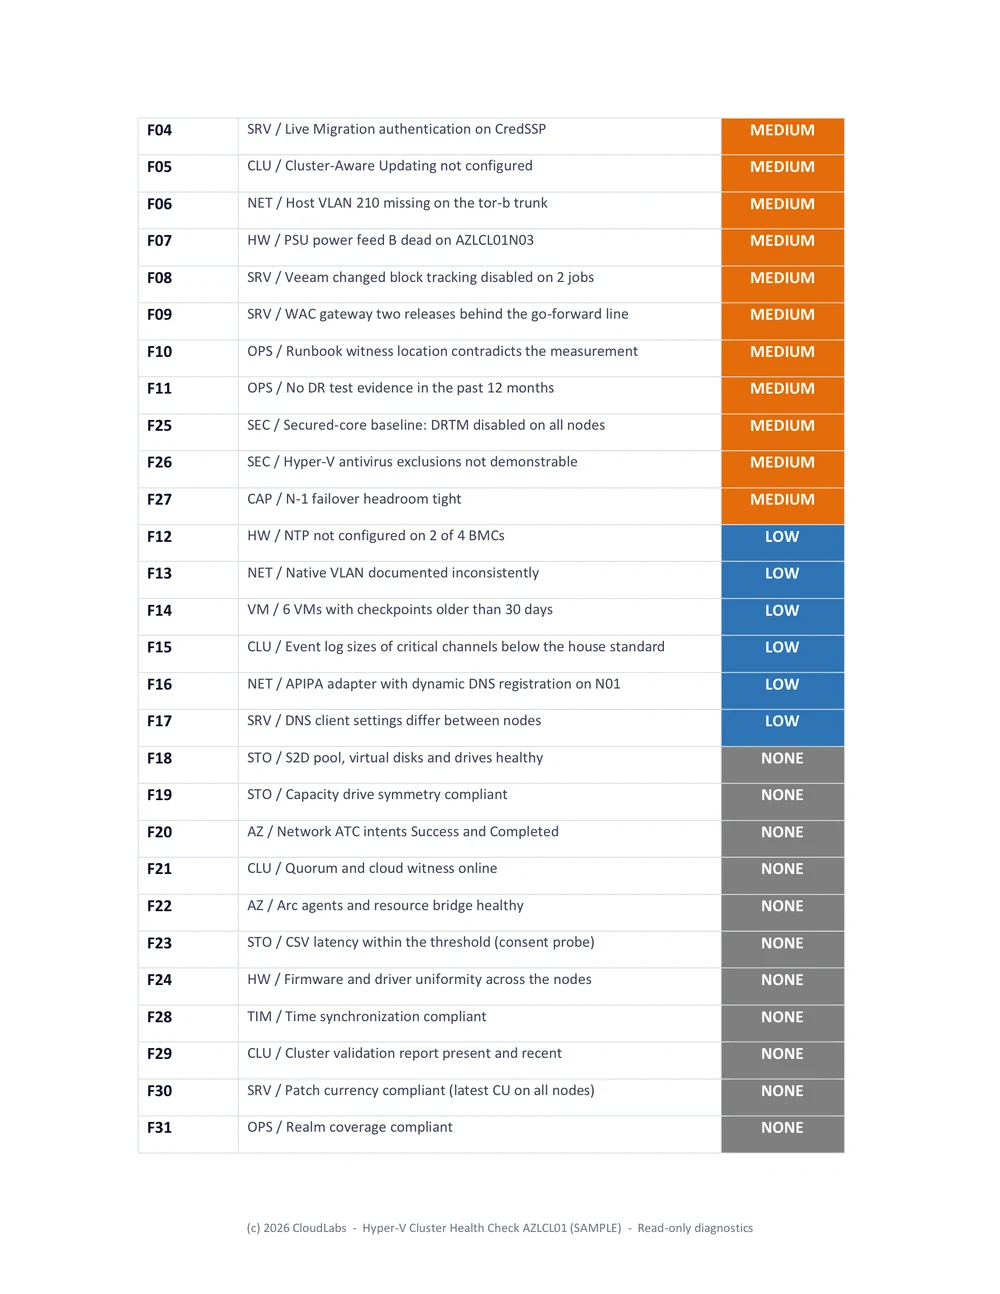
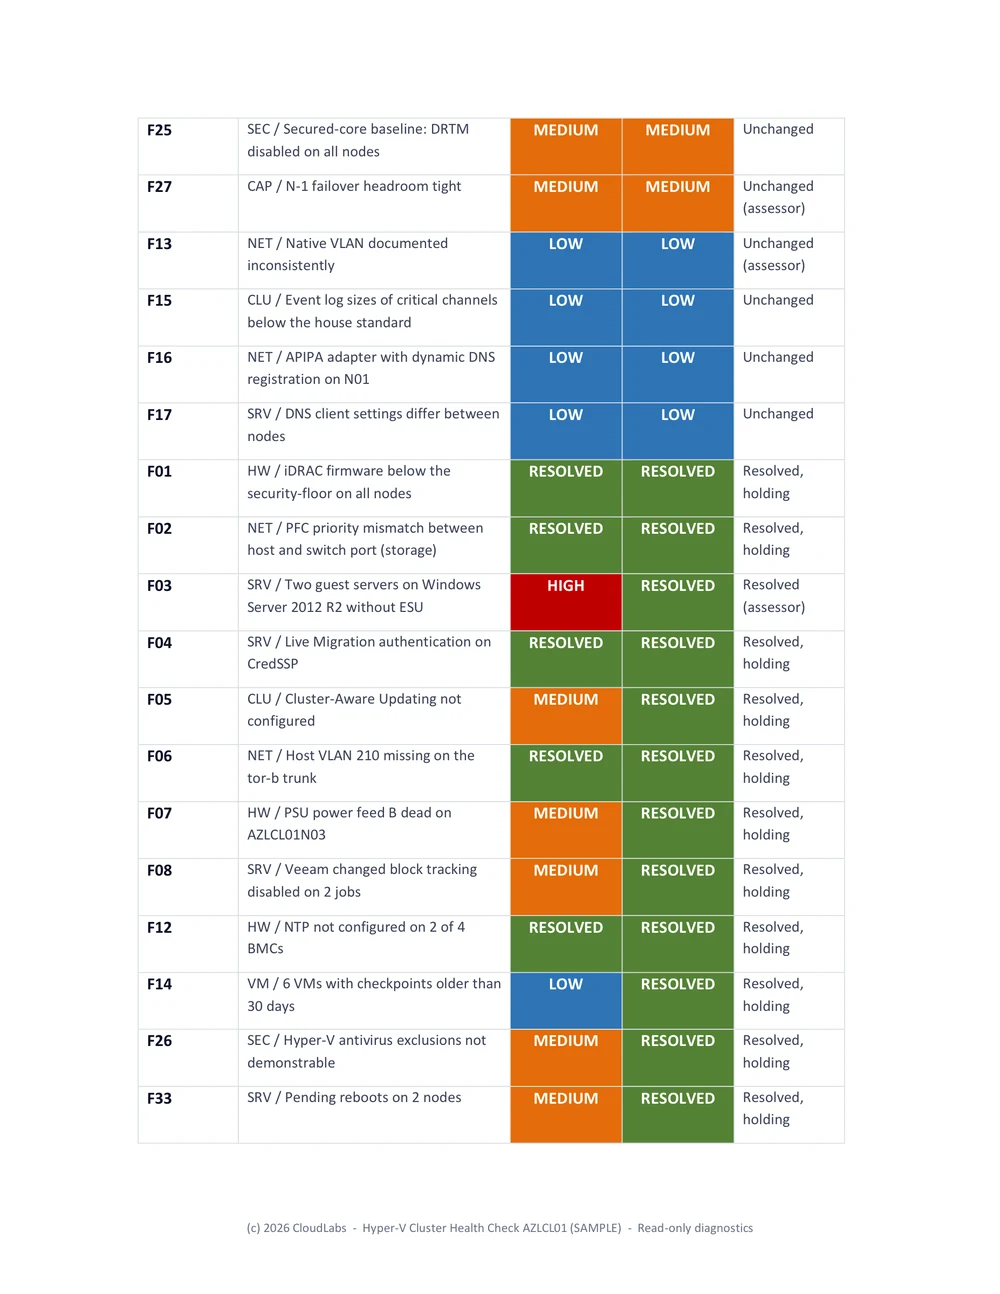
Real output
Examples from the reporting toolchain use fictitious environments and contain no customer data. Click to enlarge.
About us
ClusterTriage concentrates on Microsoft failover-cluster infrastructure rather than presenting itself as a broad IT consultancy.
40+ years in Microsoft infrastructure, more than a decade as a Microsoft MVP and a long track record in Failover Clustering and Hyper-V.
LinkedIn profile →
Performance, observability and Windows internals, with a long technical background in Microsoft platforms and enterprise infrastructure.
LinkedIn profile →Active incident
Assurance is preventive and continuous. An active outage needs a different first move: preserve evidence, identify the highest-priority signals and decide whether a full RCA is required.
The reactive entry point stays separate from the enterprise assurance proposition.
Preview ClusterDown →